Verbatim, Issue 02: Meet the People Using AI in Research
A new podcast series, what 50 working professionals really think about AI moderation, Quirk's New York, and our World Cup 2026 field study.
Last month I handed you a map. This month, I want you to meet the people navigating it.
When we talk to research, product, and insights teams, the question has shifted. It used to be, "Should we use AI in research?" Now it's, "How are other people actually doing it, and what did they learn?" So this issue is less about theory and more about evidence: practitioners sharing real work, participants telling us what the experience is actually like, and a few product updates built around how you work.
A Series: How to AI UXR, the podcast
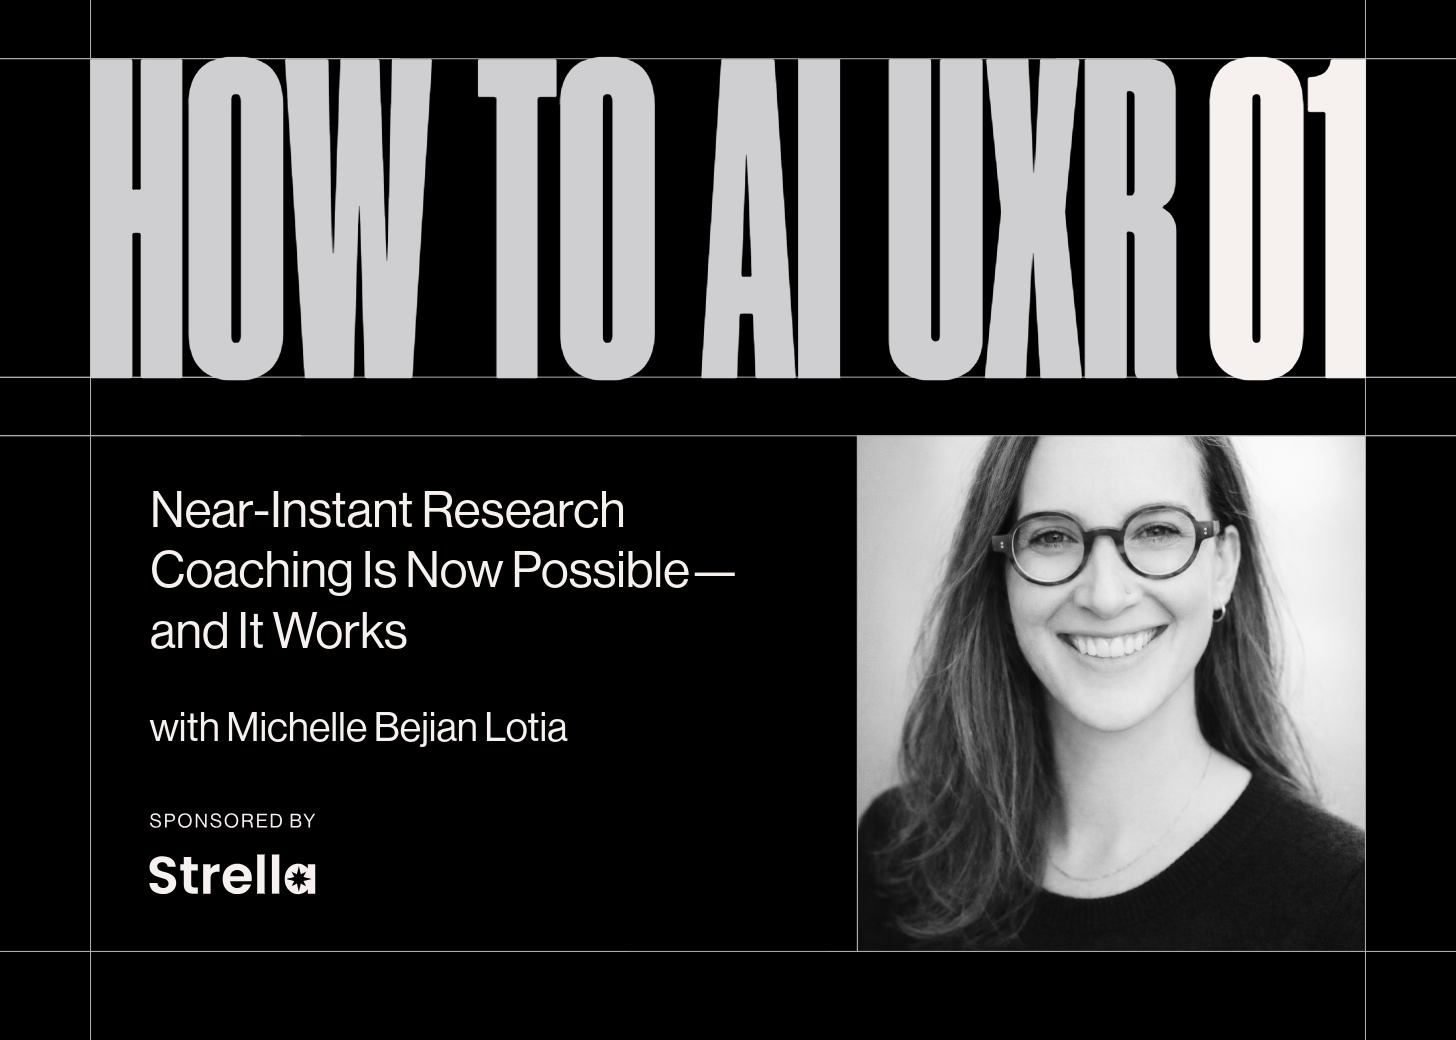
We worked with Kate Towsey and the ResearchOps Review team to turn the How to AI UXR map into a conversation. It is an 8-part video podcast, 30 minutes each, where a research practitioner walks through something real they built or figured out using AI. Plus you’ll get Priya’s take on each of the conversations halfway through the episode.
The first three episodes are live:
- Ep 1, Michelle Bejian Lotia, Ramp: Start small. Pick one specific pain point and solve it, instead of trying to boil the ocean.
- Ep 2, Daniel Gottlieb, Microsoft's CoreAI: Bringing order to the "Wild West" of custom AI tools inside a large enterprise.
- Ep 3, Nam Pham, DoorDash: Teaching AI systems to be reliable through patience and systematic design.
With five more episodes to come featuring:
- Llewyn Paine, AI expert and consultant
- Jordan Brinkman, ERGO NEXT
- Dave Chen, 1Password
- Amanda Amyx, Hatch
- Allison Robins and Brooke Sykes, Mozilla
Listen on Spotify or Apple Podcasts, and if you have not grabbed it yet, the How to AI UXR map is still a free download.
Our Take: 50 professionals' reactions to talking to an AI moderator
The most common hesitation we hear before a team runs their first AI-moderated study is about the participant: will they open up, will they trust an AI interviewer, will it feel cold?
It is a fair question, and it usually comes from the people who care most about research quality. But it rests on an assumption: that participants judge an AI moderator the same way they judge a human one. It turns out they do not.
We ran a study with 50 working professionals to find out. The overwhelming majority rated the experience a 9 or 10 out of 10, and a 5 out of 5 on whether they would do it again. What they described was not tolerance. It was ease, and often more honesty than they expected:
The pattern is consistent. Without the social weight of a live conversation, people stop calibrating to someone else's reactions, and they say the truer thing. Closer to writing in a journal than sitting across from a stranger.
Read the full breakdown, on our blog.
Catch Us in the Wild: Quirk's New York
The Strella team will be at Quirk's New York on July 29 and 30. Strella’s Head of Growth, Kelsey Brennan is hosting a fireside chat with Sarika Patel, Head of Product Research at Duolingo.
Kelsey and Sarika will get into how the Duolingo research team keeps real user understanding center stage while navigating the speed and scale of a constantly evolving app, where AI-moderated research fits in their toolkit, and how they built trust in the method.
Session: How Duolingo's Research Practice Shapes a Constantly Evolving App
When: Wednesday, July 29, 11:15am
Where: Room 5, Javits Center
If you're going to be there, come say hi to the team at Booth 327!
Strella Field Study: World Cup 2026
We weren’t just watching the world cup, we were also researching it. We talked to 35 fans, across multiple languages, about how they experience the tournament: the match-day rituals, the moments that got to them, how they decide what to bet on and which platforms they trust, and even how fans on opposite sides live the exact same moment completely differently.
It is a fun look at a few things Strella does well all at once: drawing out real emotion instead of checkbox answers, reaching people across languages, and going from a live moment to insight fast.
Here’s a preview of what we found out (full download of the study coming soon!)
In case you missed it: product updates
You can always check the changelog for the week-to-week updates, but here is what we are most excited about. The theme this month: your AI moderator can now see what your participants see.
Live and in Beta. Updates that have already landed with select customers:
- Visual task grading: assess how users performed on tasks in usability testing, not just by what they say but how they do it. Participants are given a pass/fail grade allowing you to not just hear but see where they get stuck.
- Navigation path mapping: follow your customers through live websites and prototypes, captured and mapped across every participant session.
- Card sorting: run interactive card-sort exercises inside an interview while the AI moderator probes the reasoning behind each grouping.
Coming Soon. A look at what we're building toward next, straight from the roadmap:
- Broader visual and emotional intelligence: your moderator sees and interprets what participants share on screen, live in the conversation and in your analysis.
- Tree testing: participants navigate a proposed structure while the AI moderator follows up, turning pass or fail rates into clear explanations of where navigation breaks down.
- Human-moderated studies: run interviews yourself with a human moderator alongside AI, while recruitment, recording, transcription, and analysis all stay in one place.
If you got all the way here, thanks for sticking around. More next month.
Talk soon,
Melissa